Design
Architecture, contracts and specs before any code (OpenSpec, ADRs).
A-02.1 · the set square on the plan
A-01General plan
AI Solutions Developer
I design AI systems and direct the agents that write the code. My job is the architecture, the limits and the proof: tests, metrics and cost.
A-02Method
Vibe-coding with engineering discipline. I design the system and set the limits, a fleet of agents writes the code, and nothing ships without proof.
Architecture, contracts and specs before any code (OpenSpec, ADRs).
A-02.1 · the set square on the plan
A fleet of agents writes the code in parallel. I built my own orchestrator that runs Claude Code, Codex, Gemini and Cursor Agent as a single runtime.
A-02.2 · the four orange lanes
Tests, release gates, evals and diff review. Nothing is “done” without evidence.
A-02.3 · the gate every agent passes through
Telemetry and cost per customer in production (that is what LumenAI does).
A-02.4 · linked to module M-01
A-03Projects
Seven modules on the plan. As you scroll, the agent fleet raises each one; the height of each volume follows the log of its commit count.
Python · OpenTelemetry
Turns GenAI traces into cost per customer, in US dollars, exporting only metadata, never prompts.
Three chained processors. A span stays billed to the tenant it started in.
Version 0.1.5 bills cache writes, flags an event left with no price as unpriced, alerts when a tenant reaches 80% and 100% of its budget (BudgetExporter), and adds tests against real instrumentation libraries. Version 0.1.6 keeps the budget in Redis: several processes add to one total, it survives restarts, and each alert fires once.
Checked against a real bill: on 6 real Axon Voice calls through OpenRouter (gpt-4o-mini, with caching), LumenAI's cost matched what OpenRouter charged on every call, US$ 0.00143115 in total, a difference of zero. See the table ↗
tenant globex-legal · claude-sonnet-4-6 · 40,000→2,000 tokens · cache 30,000 · US$ 0.159BGE-M3 · FAISS · BM25 · FastAPI · React · iOS
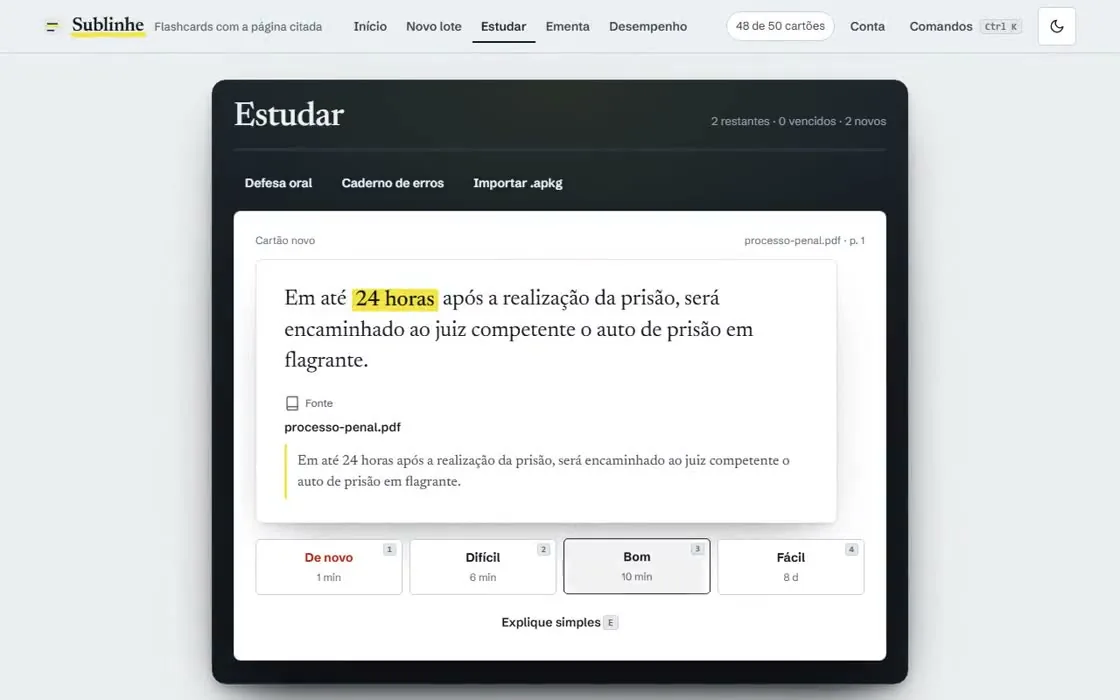
Closed-corpus RAG built for health students, the field I come from. It turns lecture material and past exams into flashcards, questions and oral practice, always citing the page.
When the material does not support an answer, it abstains.
private repository · case study in the interview
Memory for agents over MCP: personalized PageRank over a bitemporal store.
A pre-execution firewall inspects every shell command an agent proposes. Telemetry shows only numbers it actually measured.
758 commits since 13 Sep 2026
private repository · case study in the interview
A local, read-only panel that shows what a coding agent is doing without spending model tokens (ETag/304 polling).
Zero runtime dependencies. MCP widget for Claude, Codex and Antigravity.
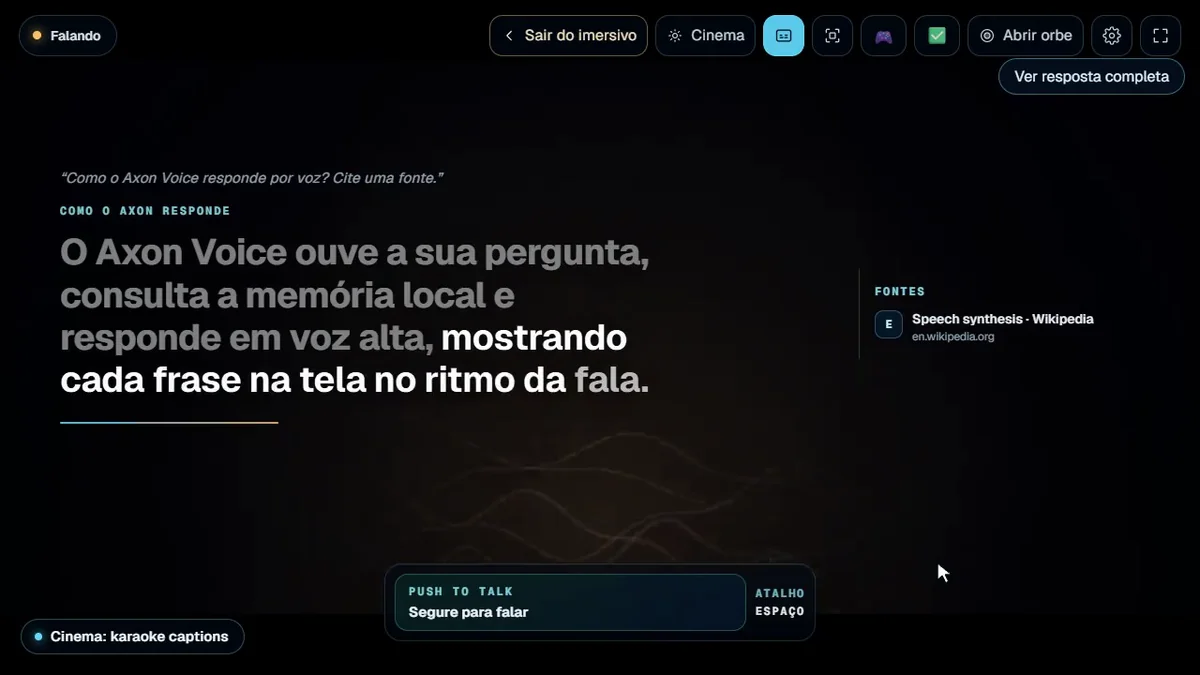
A local-first voice work partner that answers from evidence and learns from you.
voice → Whisper → parallel retrieval (vector memory · knowledge base · Neo4j graph) with RRF fusion → local LLM (Ollama) or cloud → speech, sentence by sentence
It cites the exact page or says it does not know (corrective RAG with LangGraph). What you state goes into a time-aware knowledge graph. An always-on-top orb: hold Right Ctrl to talk from any app.
1,622 tests · Playwright E2E · no test reaches a cloud service
Case study and demo video (Portuguese) →
Private repository
TypeScript · Electron · React · Python FastAPI
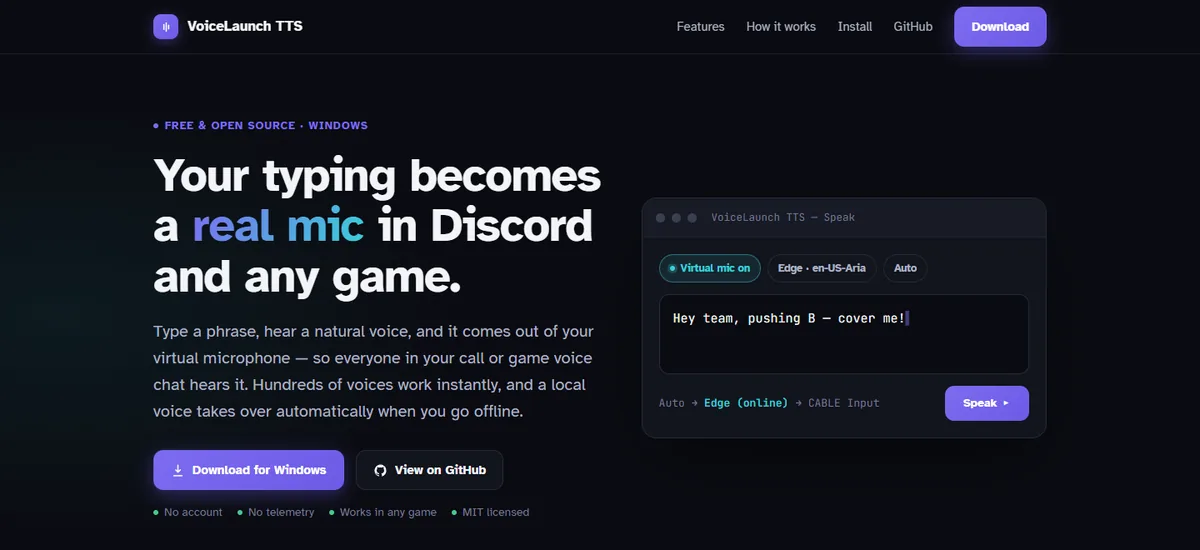
Turns typing into a real microphone for Discord and games.
Edge TTS online, with automatic fallback to local Kokoro/Piper when the network drops. The virtual microphone (VB-Cable) is bundled.
165 Vitest tests · Playwright E2E · accessibility features
Next.js 16 · Mastra · GPT-6 Luna (OpenRouter) · Drizzle + Turso · React 19 · Redux Toolkit
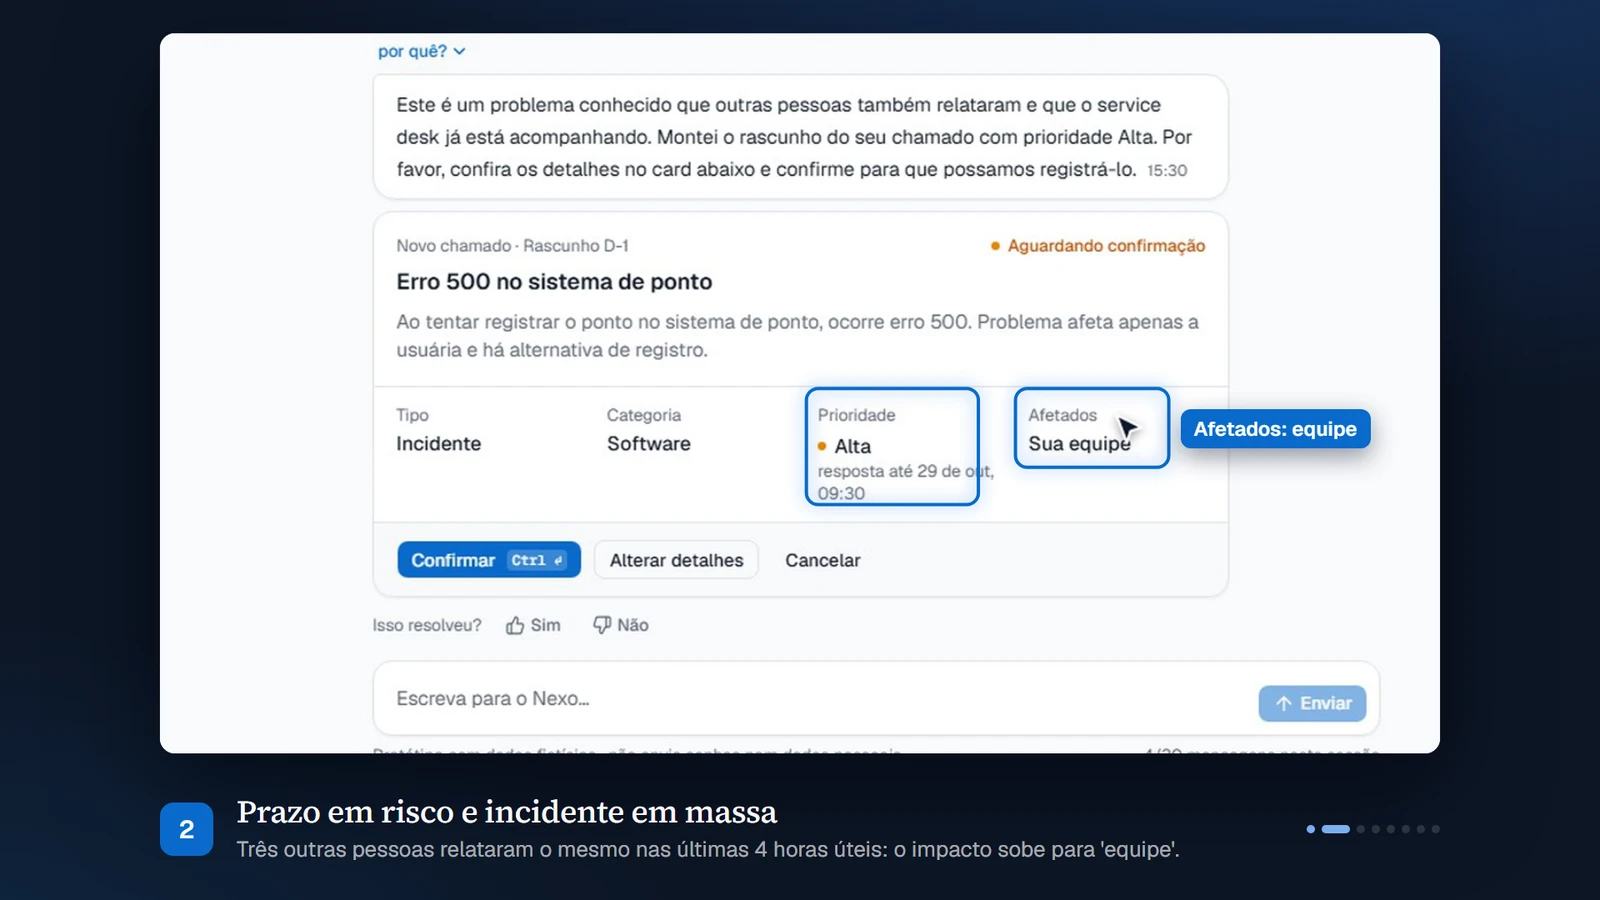
An IT service-desk agent, built for the technical challenge of a hiring process. Every answer shows what it understood, what it did and why.
The employee talks to the agent, which tries to solve the issue through the help center with hybrid search and asks “Did this solve it?”. When it doesn't, it drafts the ticket for the person to confirm, warns when the deadline is at risk and notices when several people report the same problem.
On the other side, the analyst follows conversations in real time (SSE), with a conversation report, a suggested reply and the indicators. If GPT-6 Luna fails, the step falls back to Gemini Flash Lite and the trace says which model answered.
The service-desk rules (priority, deadlines, confirmation, privacy) live in tested code, and code decides which tools the model may use at each step. The chosen model was later checked in a benchmark of 7 models, with real cost measured.
hybrid search 84% → 94% · simulated employee pass^1 0.72 → 0.93 · 486 MB Docker image, 25/25 on the smoke test · CI on CircleCI and CD with Komodo pulling from Docker Hub, running
Read the case study →Try the demo ↗Repository ↗Watch the demo video →
A-04Activity
GitHub · 26 Oct 2025 → 27 Oct 2026
Key plan · real calendar, 53 weeks × 7 days
On the 3D plan, each day becomes a stack of blocks (1 block = up to 5 contributions) that the agents pile up. Hover over a stack to see the day.
A-05Path
I started out in medicine. Today I am preparing for the tech job market by building AI systems end to end: the agents write the code, and I answer for the architecture and the proof. A degree in technology comes next.
Medicine, the field I come from.
lumen-ai-core published on PyPI.
Axon Voice closed for local use.
VoiceLaunch 1.3, first open-source release.
SynapseEngine starts.
Sublinhe, MVP closed.
LumenAI SDK, deep review: billed OpenInference spans, a proper flush, a reproducible demo and a dashboard.
Axon Voice, new version: answers with sources, a knowledge graph and an always-on-top orb.
Nexo Assist, an IT service-desk agent, delivered as a technical challenge.
A degree in technology and my first opportunity in the industry.
A-06Contact
Brazil · open to first opportunities.