M. MachucaAI Solutions Developer
PT

← Portfolio · M-07

M-07Case study

Nexo Assist

An IT service-desk agent, built as the technical challenge of a hiring process.

The employee describes the problem in their own words. The agent checks their tickets, searches the help center, opens or updates a ticket once they confirm, and calls an analyst when it needs to. Every answer shows what it understood, what it did and why.

Public demo, in Portuguese: sign in with one click as Ana (employee) or Rafael (analyst), with made-up data. Up to 100 messages a day across all visitors.

My role
Architecture, rules, acceptance criteria and evidence. Coding agents wrote the code, in small verified increments.
Delivered
28 Oct 2026 · 154 commits
Stack
Strict TypeScript · Next.js 16 · Mastra · GPT-6 Luna (OpenRouter) · Drizzle + libSQL/Turso · Redux Toolkit · Vitest · Playwright
Code
Public on GitHub, with specs, validation reports and the demo video. The docs are in Portuguese.

Nexo Assist in 60 seconds

The problem
A fictional company of about 2,000 employees has an IT team buried in triage: tickets without context, duplicates and wrong priorities.
What the agent does
It talks to the employee, searches the help center, opens or updates a ticket once they confirm, and calls an analyst when it needs to. Every answer shows what it did and why.
The proof
36/36 evals with the real model, 21/21 in the red team and 472 tests without an LLM, each number with its source in the repository.
See it work
Public demo ↗ in Portuguese, one click as Ana or Rafael, or the 5:28 video.

N-01The challenge

What was asked

A fictional company of about 2,000 employees has an IT team buried in triage: tickets without context, duplicates, wrong priorities, and simple questions waiting in the queue.

The hiring process asked for Nexo Assist, a chat agent that answers questions from the help center, looks up and opens tickets, and hands the conversation to an analyst when needed. On the other side, a console where the analyst takes over with the agent paused, then hands it back or closes it.

The part the brief itself calls the most important: being able to understand, in every answer, what the agent did and why.

Requirements

  • Strict TypeScript; Mastra as the agent framework; any LLM, with the choice explained.
  • Service-desk rules: priority from impact and urgency, deadlines in business hours, no duplicates, reopening within 7 days.
  • A simulated ticket service, separate from the agent, behaving like a legacy system that sometimes goes down.
  • Conversations, tickets and the state of each conversation surviving a restart.
  • Security and privacy (one person's tickets never shown to another) and the cost per conversation under control.
  • Runs locally with a few commands and follows the screen prototype.

N-02Architecture

The system plan

The same structure as the repository's src/. Pick a step and the camera flies to it; on a phone, the steps advance as you scroll.

  1. The browser on the left. The layered app in the middle. Around it, the model, the database and the optional pieces. At the bottom, delivery. A dashed line is an optional piece.

  2. Lean DDD. Dependencies only point inwards: app/, agent/ and infrastructure/ depend on application/, which depends on domain/. The domain knows nothing about Next, Mastra or the database, so priority, deadlines and reopening are tested without mocks. Infrastructure implements the application's ports, and a single file wires the pieces together (container.ts).

  3. A Mastra agent with 11 tools: recordUnderstanding, searchHelpCenter, askDiagnosticCheck, listMyTickets, getTicket, draftNewTicket, draftTicketUpdate, confirmDraft, cancelDraft, offerQuickReplies and transferToAnalyst. The first step is forced to record its understanding (intent, confidence and reason), and code decides which tools exist at each step. The model is GPT-6 Luna, through OpenRouter; if it fails, the step falls back to Gemini 3.5 Flash Lite and the trace says which model answered.

  4. Drizzle on libSQL: SQLite in development, Turso when deployed. Conversations, messages with their trace, drafts and tickets survive a restart. The legacy ticket system is simulated by a decorator that fails 15% of calls; the service retries without creating duplicates. The search embeddings are cached in the database.

  5. The chat receives each turn as NDJSON: steps, cards and text. The analyst console, and the chat while an analyst is attending, open an SSE stream. The server checks a cheap database signature every second and says when something changed. If the stream drops, the screen falls back to polling on its own.

  6. Production runs on Vercel with the database on Turso, published from a git archive of the latest commit. Alongside it, a Docker image with a smoke test and the CircleCI → Docker Hub → Komodo path. That path has run since 29 Oct 2026: on every push to main with green CI, Komodo pulls the new image within 10 to 20 minutes.

  7. OpenTelemetry tracing with the GenAI conventions, ready for Langfuse, and OpenID Connect SSO (PKCE, state, nonce, JWKS). Both ship turned off and were tested against local servers that follow the protocols, not against real Langfuse, Entra ID or Okta.

Source: docs/specs/04-arquitetura.md · src/agent/tools/index.ts · docs/DEPLOY.md

N-03What was built

Both sides of the desk

For the employeeSolved without a queue

  • They write the way they talk. The agent searches the help center and asks “Did this solve it?”; the answer feeds the resolution indicator.
  • It finds a ticket without its number and warns when the deadline is at risk (75% of the business-hours deadline), showing the math.
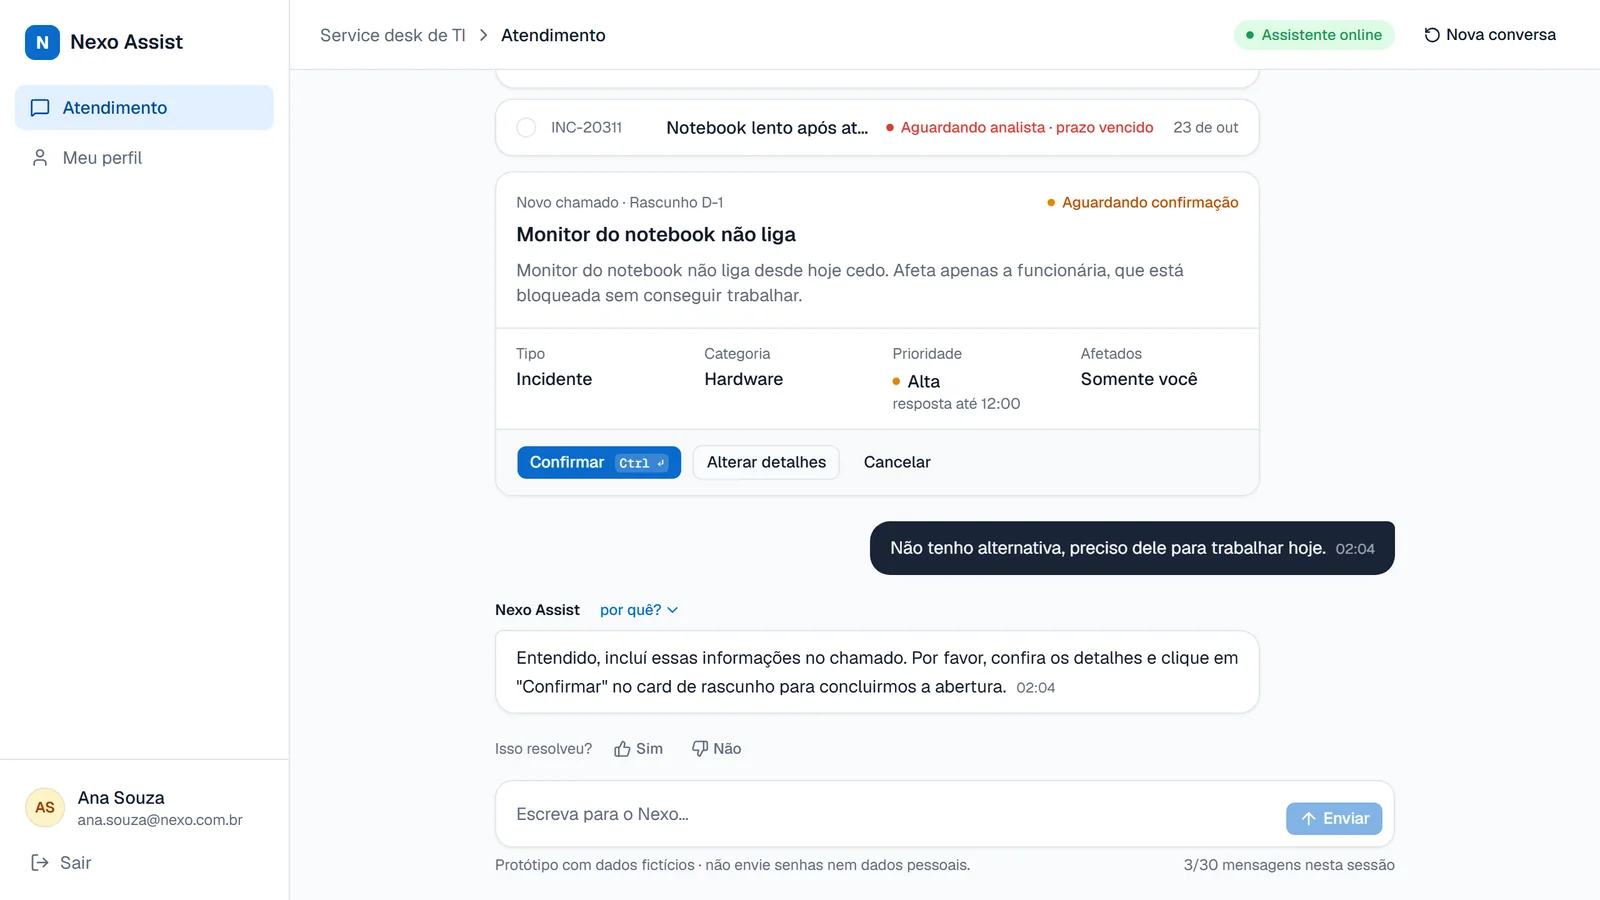
  • It builds a draft with priority and deadline computed in code. Nothing is created before the person confirms; “Change details” recalculates on the server.
  • When three or more people report the same problem within 4 business hours, it raises the impact to “team” without revealing who reported it.
  • High frustration brings up a “Talk to an analyst” button. An explicit request, a critical case, an overdue ticket or doubt that persists hands the conversation over.
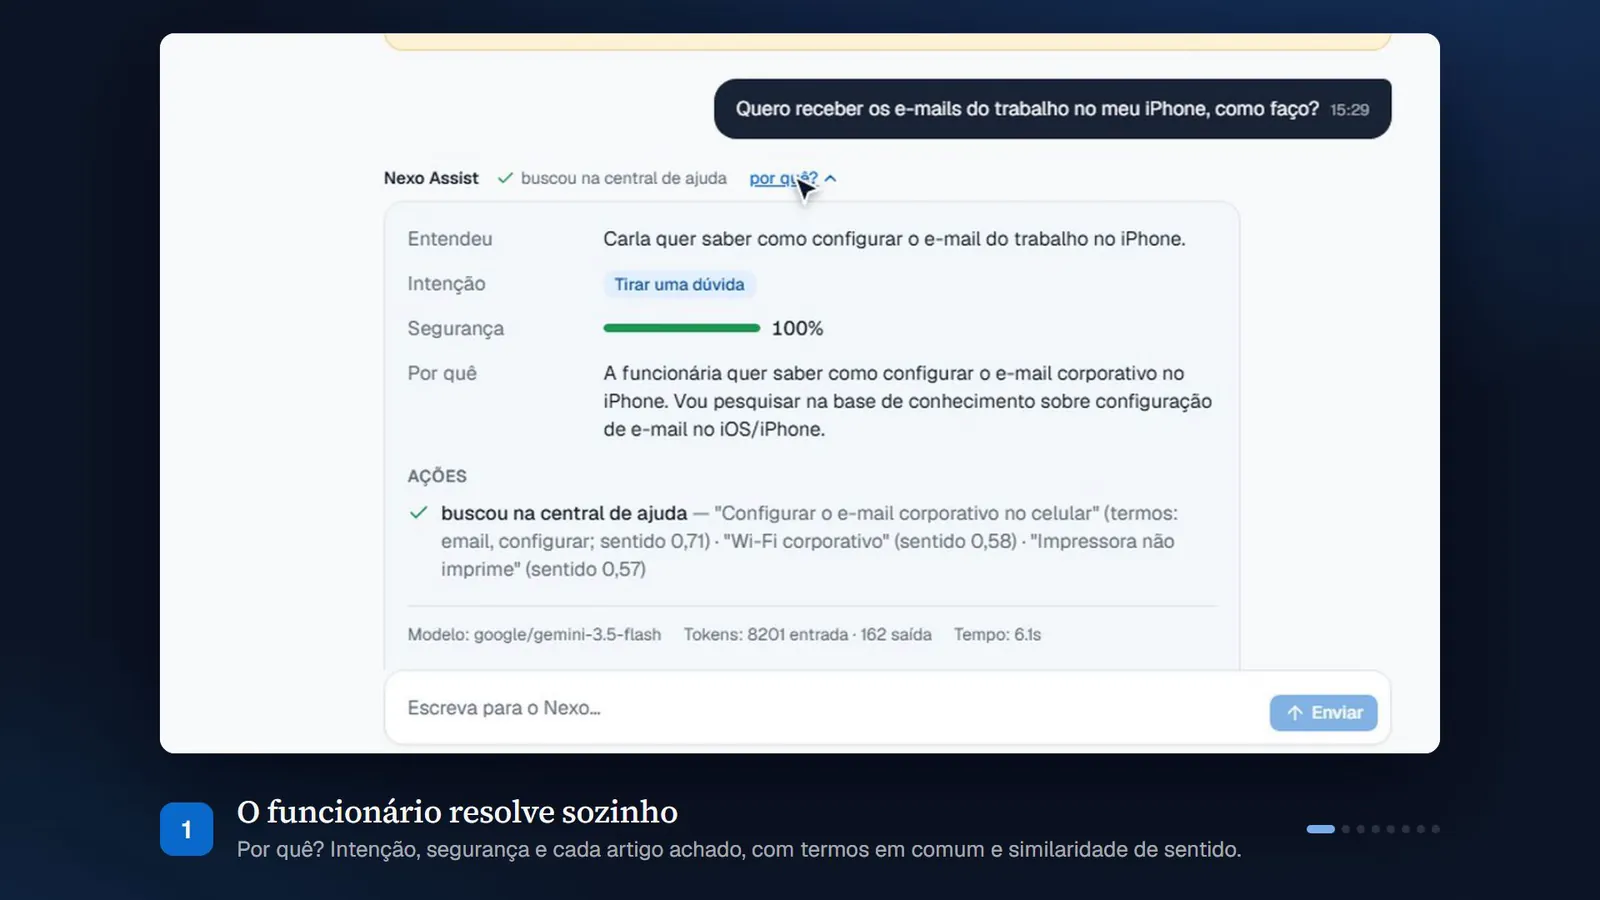
  • The “why?” panel on every answer: intent, confidence, reason, tools with input and output, rules that fired, model, tokens and time.
Ticket draft in the chat: notebook monitor will not turn on, hardware incident, High priority with a response by 12:00, only the employee affected, and the Confirm, Change details and Cancel buttons
From the app · draft with priority and deadline from code
The why? panel open in the chat, in Portuguese: what the agent understood, the intent, 100% confidence, the reason and the articles the search found, with each one's similarity
From the demo video · the “why?” panel of one answer (the app is in Portuguese)

For the analystArriving with context

  • A queue with signals: high frustration, possible mass incident, reason for the handoff.
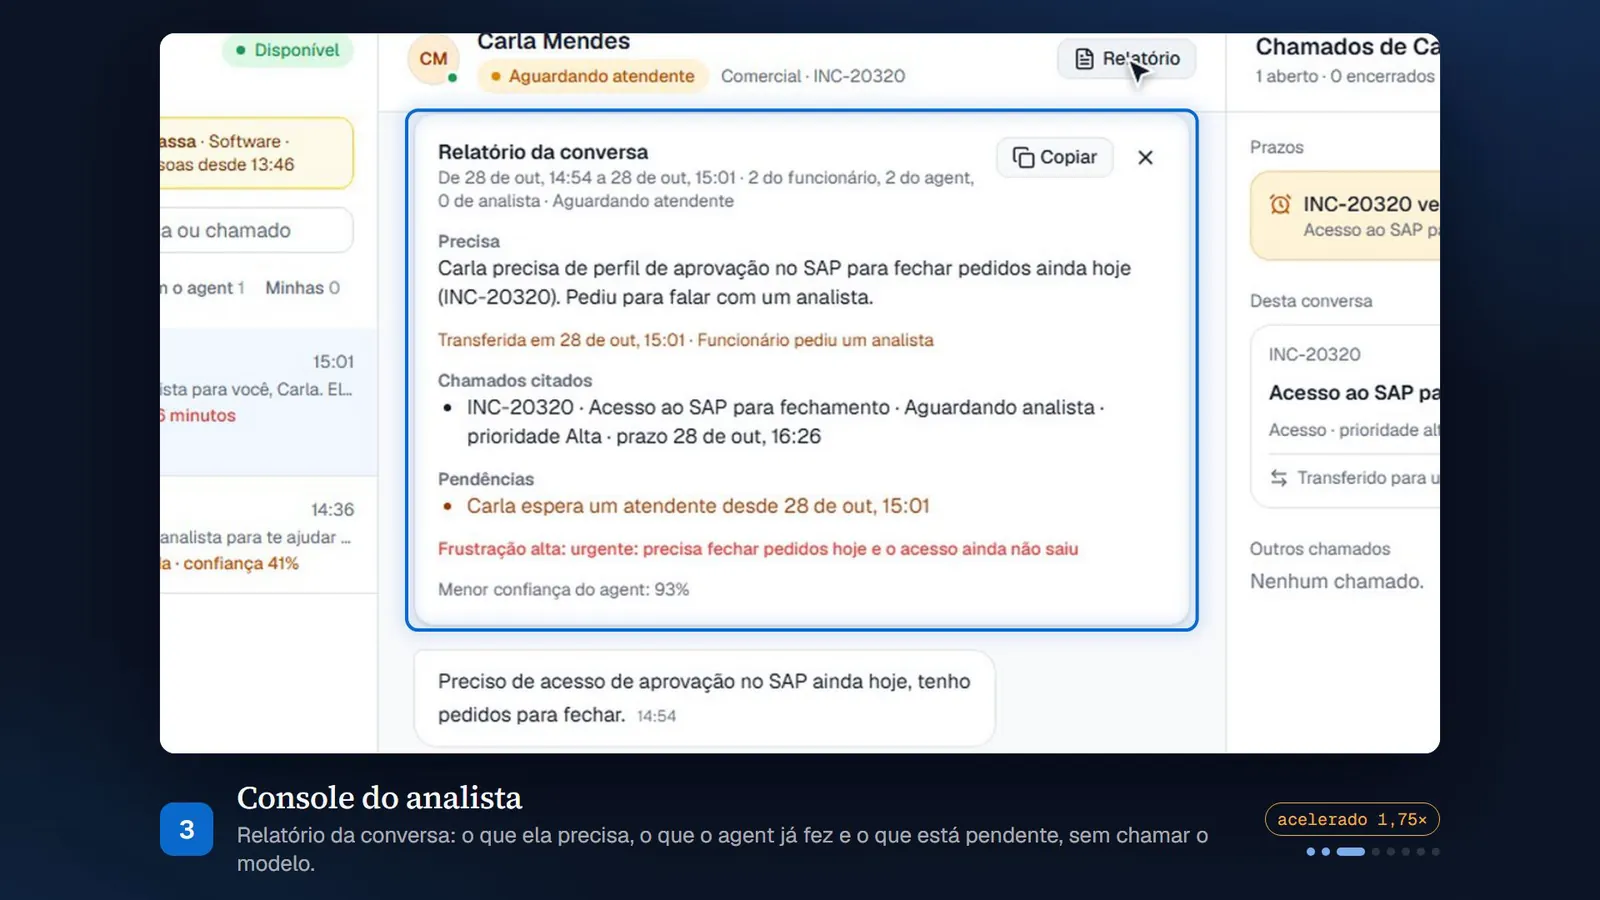
  • The conversation report: what the person needs, what the agent already did and what is pending. It is built from the history and the traces, without calling the model.
  • Takes over with the agent paused, hands it back or closes it. The database only accepts the change if the state is still the expected one, so analyst and agent never step on each other.
  • “Suggest a reply”: the model writes, the analyst reviews before sending.
  • Everything in real time over the SSE stream, with polling as the fallback.
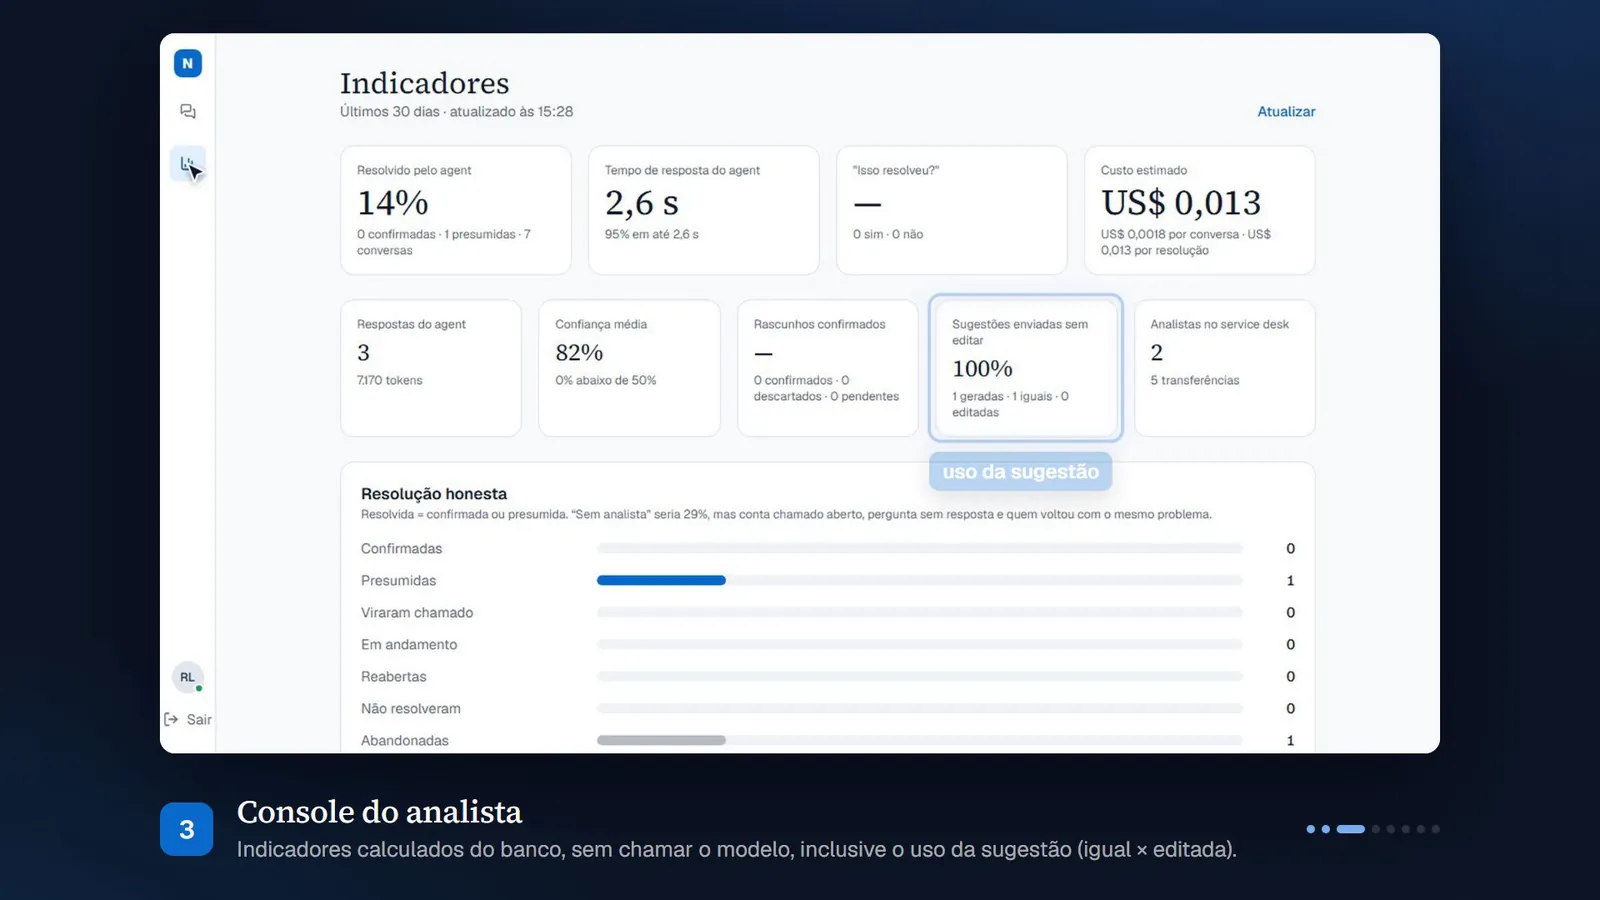
  • Honest indicators: confirmed resolution kept apart from presumed, not counting open tickets or people who came back with the same problem, and help-center gaps with personal data masked.
Analyst console with the conversation report open, in Portuguese: what the employee needs, the cited ticket with High priority, what is pending and the high-frustration signal
From the demo video · conversation report in the console
Indicators screen, in Portuguese: resolution by the agent, response time, estimated cost and honest resolution split into confirmed, presumed and abandoned
From the demo video · indicators computed from the database

N-04Demo video

From conversation to ticket, and from ticket to analyst

In 5:28, the employee solves a problem alone, the agent drafts the ticket and the analyst takes over in the console. The app footage is real, recorded on 28 Oct with Gemini; waits for the model are sped up and marked as such. Diagrams and numbers are animations, updated on 30 Oct: relevance-judge search, GPT-6 Luna and the current numbers, and each number shows its source in the repository. It has original background music and sound effects. The video is in Portuguese.

H.264 · 1920×1080 · 27 MB · plays only when you press play · Portuguese narration with a synthetic voice (Fish Audio) · original score · sound effects: Pixabay · also in the repository ↗

N-05Decisions

What I chose, and why

D-01 · model

From Gemini to GPT-6 Luna, decided by a benchmark

I picked Gemini for reliable tool calling (including the tool forced on the first step, which the “why?” panel depends on), low latency with reasoning set to minimal, and a cost of about one US cent per answer.

Then I replaced the qualitative choice with data: I ran the production agent with 7 models, measuring effectiveness, quality (G-Eval with 2 judges), latency and real cost, under a US$ 1.80 cap. GPT-6 Luna tied with Gemini within the confidence intervals and cost 26 times less. I kept Gemini while it had credit. When the Google credits ran out, on 29 Oct, I switched to Luna with one environment variable, after confirming it in the evals: 36/36.

7 models · 24 conversations per model · Luna 26× cheaper, same quality · Flash Lite as fallback

D-02 · search

Search that knows when an article does not apply

The help center is searched by meaning (embeddings) and by keywords. When the top result does not stand out from the second, the search returns nothing: a look-alike article leads the agent to a wrong answer, and asking is better.

I measured it on 50 questions written the way an employee would, including questions with no right article. A set of 17 was written only after the choice, to check it was not overfitted. On that set the overall score tied, and the report says so.

The diagnostic articles exposed the limit of embeddings: they find the topic, not whether the article applies. “I'd like a wireless keyboard” landed on the repair article, and “the fan is making noise” got “Computer won't turn on”. Search became two steps, as in Corrective RAG: hybrid search brings 5 candidates and a cheap model says which one applies, which one maybe does, or none. Before fixing it, I wrote 18 request × fault × not-covered questions and froze them in a commit. I compared rerankers, thresholds and a judge over the whole catalog; a threshold only worked at one exact value, so the categorical decision stayed.

81 questions: 56 → 78 right · wrong article: 22 → 0 · frozen set: 9/18 → 18/18 · US$ 0.00025 per search · without the judge, falls back to the margin

D-03 · guarantees

Rules in code, not in the prompt

The model decides what to do. Whatever must be guaranteed lives in tested code: priority from the impact × urgency matrix, deadlines in business hours, mandatory and atomic confirmation, reopening only within 7 days, and identity taken from the signed cookie, never from a model argument.

Which tools exist at each step is also decided in code, following the action-selector pattern. A malicious text can change what the model wants to do, but not what it is able to do. The prompt only handles how to talk.

step-policy.ts · domain/priority.ts · domain/business-time.ts · draft-service.ts

D-04 · measurement

Honest evals

The evals check the database state, not only the text of the answer. Each attack runs 3 times, and passing 1 out of 3 counts as a failure. When Gemini returned a 503 inside the stream, an attack could “pass” without the model having answered; that now counts as a provider failure, reported separately.

The simulated employee (pass^k, as in τ-bench) is published with the result it gave, even when it is low. In the first round it found four real bugs, such as opening a ticket from a quick reply that was not a “yes”. Each one became a rule in code with a test, not a prompt tweak, and the next round was measured the same way.

database checked · attacks × 3 · provider failures kept apart · pass^1 0.72 → 0.93 and pass^3 0.50 → 0.80 after the fixes

N-06Quality and evidence

The numbers, with sources

Unit and E2E tests run without an LLM. Anything that depends on the model runs against the real model and has a report with the question, method, numbers and limits.

Round of 30 Oct 2026, on the repository's main

Show the numbers and their sources
unit tests
472
Vitest, no LLM: deadlines, priority, conversation states, privacy, duplicates, CSRF, OIDC against forged tokens, pass^k.
README · npm test
E2E tests
42
Playwright against the production build, no LLM: login and SSO, handoff, report, indicators, real time, errors.
README · npm run test:e2e
evals with the real model
36/36
Intent, expected and forbidden tools, handoff, critical case and data leaks. Among them, 8/8 attacks, 6 scenarios taken from the simulated employee’s findings and 2 diagnostic-check scenarios. Run with GPT-6 Luna, the production model since 30 Oct: the one scenario that failed with it assumed Gemini skipping self-service and was fixed in the test, not in the agent.
docs/validacao/README.md
red team, mapped to OWASP
21/21
7 attacks × 3: injection, data leaks, acting without confirmation, system prompt, goal hijack. Indirect injection through a help-center article: 3/3.
docs/validacao/RED-TEAM.md
simulated employee
0.93 pass^1 · before 0.72
A model plays the employee, with facts it only shares when asked. Three rounds on the same day: 0.72 / 0.50 → 0.93 / 0.80 → 0.93 / 0.80, the third with one persona re-run after its fix. With 10 personas × 3, 28/30 conversations right; pass^3 0.50 → 0.80 (8/10 personas right in all 3 runs). The first round found real agent bugs, fixed with rules in code and tests, not prompt tweaks.
docs/validacao/SIMULACAO.md
help-center search
56 → 78 of 81 · 0 wrong article
Keywords against hybrid search with a relevance judge, on four sets; 18 request × fault × not-covered questions frozen before the fix: 9/18 → 18/18.
docs/validacao/BUSCA.md
SSE against polling
263–580 ms
Median with the stream, against 1,505–1,684 ms with the old polling. The E2E test fails if p95 goes over 2 s.
docs/validacao/TEMPO-REAL.md
suggested reply
9/9
3 conversations × 3, with no invented number or action in the analyst's draft.
docs/validacao/README.md
security reviews
4
Before and after deploying, 42 black-box checks against production, and a round with third-party audit skills. npm audit with no vulnerabilities.
docs/DEPLOY.md

N-07Delivery

From commit to live

Vercel, in production

The app is live on Vercel, with the database on Turso, as a public demo since 29 Oct 2026. Cost is capped in code: up to 100 messages a day across all visitors, per-person limits and a total ceiling, all reserved in the database before the model is called. The link-based access gate stays in the code: without the PUBLIC_DEMO switch, Vercel requires the link again.

Each release comes from a git archive of the latest commit, so nothing outside git is uploaded. Usage caps per person, per day and in total are reserved in the database before the model is called.

git · maindeploy-prod.ps1Vercel + Turso

live

Docker, CircleCI and Komodo

The Docker image (Node 24, non-root, database on a volume) is 486 MB and passed all 25 smoke-test checks: it migrates, seeds the sample data, logs in for real, checks permissions and restarts without losing data.

CircleCI runs types, lint, tests, E2E and the same smoke test, then publishes the image to Docker Hub. Komodo checks the digest of latest every 10 minutes and redeploys. CI never publishes to Vercel.

git · mainCircleCIDocker HubKomodo

running

On its first run, on 28 Oct 2026, CircleCI caught an error my machine was hiding: the LayoutProps type that Next 16 generates in .next/ does not exist in a clean clone. The fix was to run next typegen before tsc. The image is on Docker Hub, and Komodo runs it only on my machine, at 127.0.0.1:3300. docs/DEPLOY.md

N-08Still open

What is left

Show what is still open
  • What the simulated employee caught

    Every bug from the three rounds became a rule in code, with tests: confirmation must be explicit (and a “Sim, é esse mesmo”, “yes, that’s the one”, that only identifies the ticket reopens nothing), a different problem gets a new ticket, Outlook is filed under E-mail, an analyst is offered only with a reason (a deadline that misses the need, an overdue ticket or frustration) and the workaround question comes before the priority. Re-run after the 29 Oct fixes, senha-sap and vpn-reuniao passed 3 out of 3, and so did the reopen eval. What remains is the model’s own variance: in the full suite on 29 Oct, one mass-incident scenario failed once and passed 3 out of 3 when repeated.

  • Image delivery is local only

    The CircleCI → Docker Hub → Komodo path runs, but Komodo lives on my machine, on loopback only: it proves image delivery, it is not a second public environment. Production stays on Vercel, published by hand.

  • Small sample

    10 personas × 3 runs is too few to pin down a rate. The numbers show the direction, not a guarantee.

  • Model switch

    The benchmark recommends GPT-6 Luna after a confirmation round against Flash Lite. The switch has not been made.

  • Repeated calls

    Tracing showed the model calling the understanding tool several times in parallel on the first step. Only the first one counts, but the others spend tokens.

  • Evals outside CI

    They run by hand because they call the real model. The next step is running them in CI with a minimum threshold.

  • Real services

    SSO was only tested against a fake provider, and tracing against a local collector. Logging out does not revoke the JWT on the server, and the console needs a wide screen.

Try the demo ↗ See the repository ↗ Contact on LinkedIn ↗ ← Back to the portfolio